The Data Stack Is the Biggest Non-AI Employer You Are Ignoring
SQL out-mentions React and Kubernetes at 411. Under every AI team is a data team — and the modern data stack is hiring at a scale that rivals AI itself.
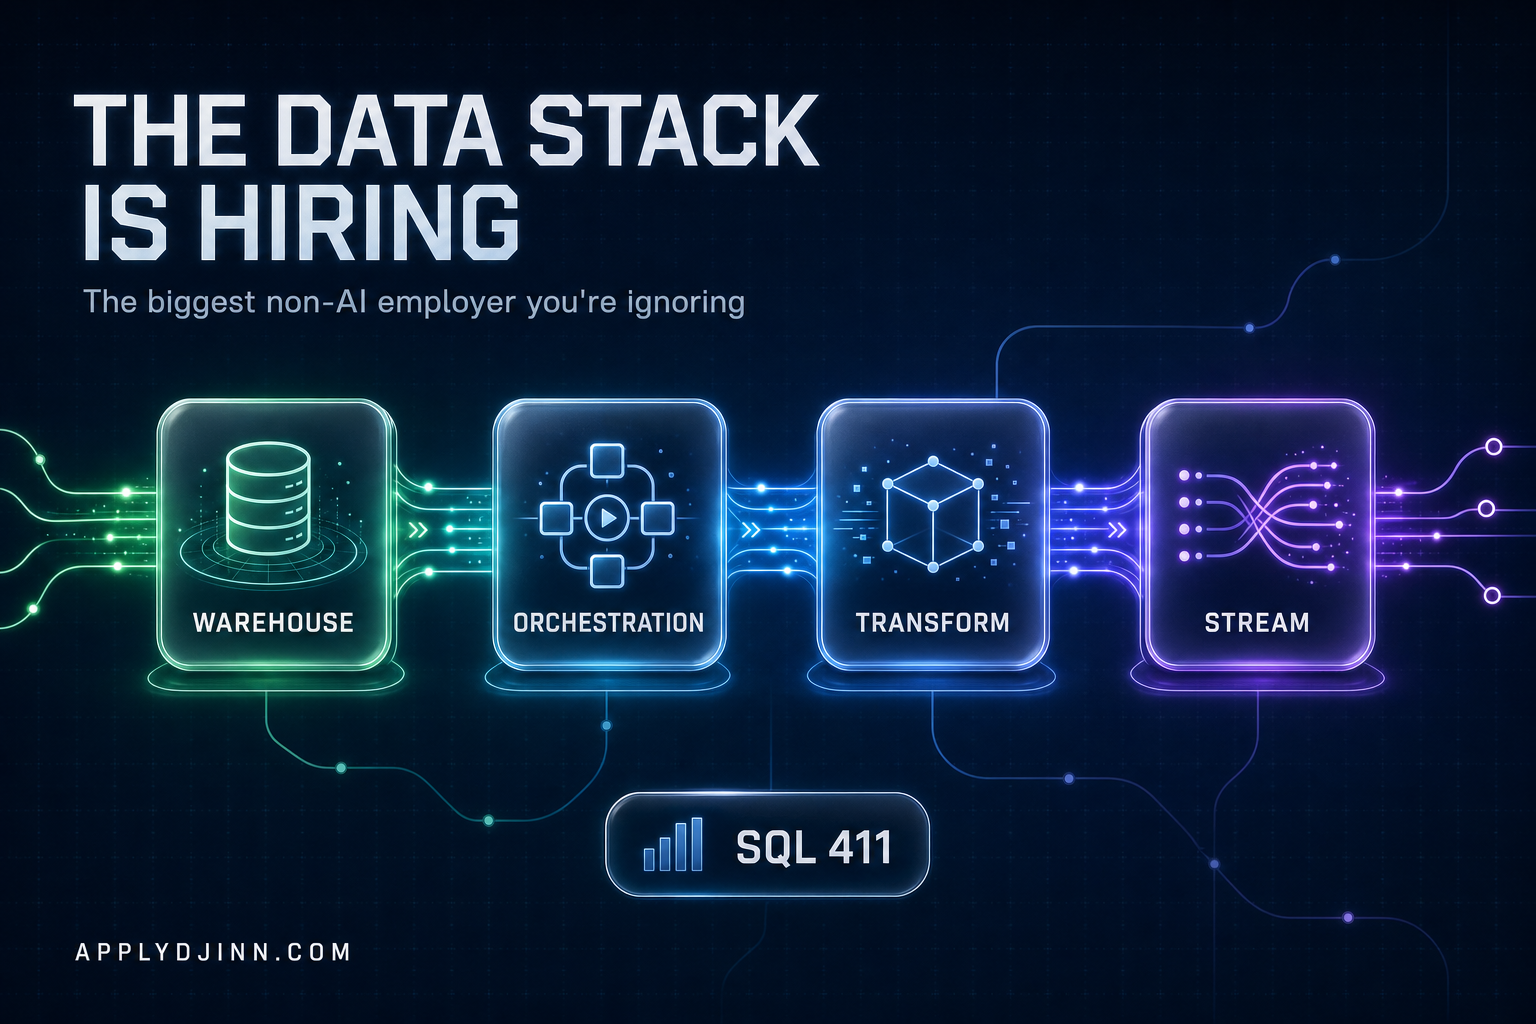
AI gets the headlines. But underneath every AI team is a data team, and the data stack is hiring at a scale that quietly rivals it. If you want durable demand without fighting the entire market for the same AI-product roles, this is the lane.
The backbone numbers
- SQL — 411 mentions. More than React. More than Kubernetes. The single most universal hard skill after Python.
- Kubernetes — 393. The runtime the data platform ships on.
- Named tools cluster tightly into a stable "data platform" imprint: Snowflake, Databricks, Airflow, Kafka, Spark, and dbt keep appearing together.
Why data engineering is the best-kept secret
- Every AI initiative needs it first. You cannot train or serve models on bad pipelines. Data engineers get hired before the ML team scales.
- It is durable. Dashboards, pipelines, and warehouses are load-bearing infrastructure, not discretionary product. They do not get cut when budgets tighten.
- The skills are concrete and teachable: SQL to real depth, one warehouse, one orchestrator, and the basics of streaming.
The modern data stack, decoded
- Storage and compute: Snowflake or Databricks — know one deeply.
- Orchestration: Airflow (or Dagster / Prefect) — how pipelines get scheduled, retried, and observed.
- Transformation: dbt — SQL-based, the lingua franca of analytics engineering.
- Streaming: Kafka — for when batch is not fast enough.
- The glue: Python, and increasingly a working knowledge of Kubernetes.
A path in
- Get genuinely good at SQL — window functions, query plans, data modeling. This alone clears most bars, and most people are lazier about it than they admit.
- Learn one warehouse and one orchestrator end to end on a real dataset.
- Ship one pipeline you can talk about: source → transform → serve, with tests and monitoring. That artifact is worth more than any certificate.
The overlap with AI
Data engineering is the on-ramp to the AI infrastructure layer we described in our 61% report. The same pipelines that feed dashboards feed feature stores and retrieval systems. Start in data, and the door to AI infrastructure is already open — without competing in the most crowded room in tech.
Figures are live vacancy mentions across 3,383 active postings, ApplyDjin, July 2026.